Der Workstation-Blog
AI Agents
Beiträge mit dem Tag AI Agents.
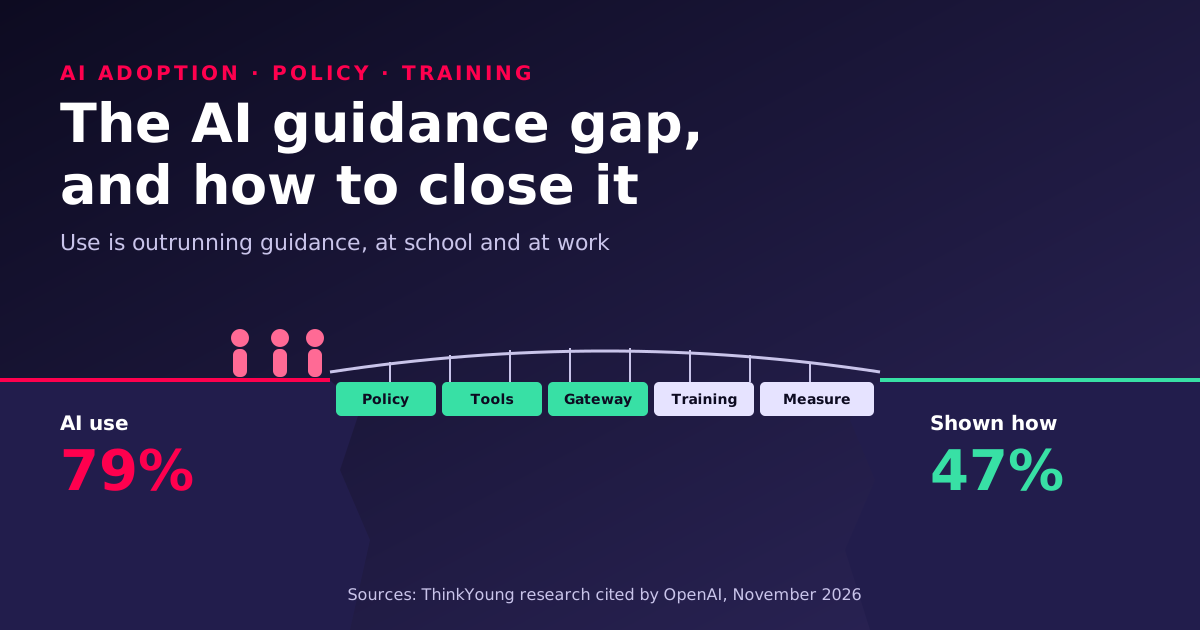
The AI Guidance Gap: Use Outpaces Training at School and at Work
79% of students use AI for homework but only 47% were shown how, according to ThinkYoung research cited by OpenAI. Workplaces show the same gap. A 90-day playbook for business leaders: policy by data class, approved tools, a gateway, role-based training and usage metrics.
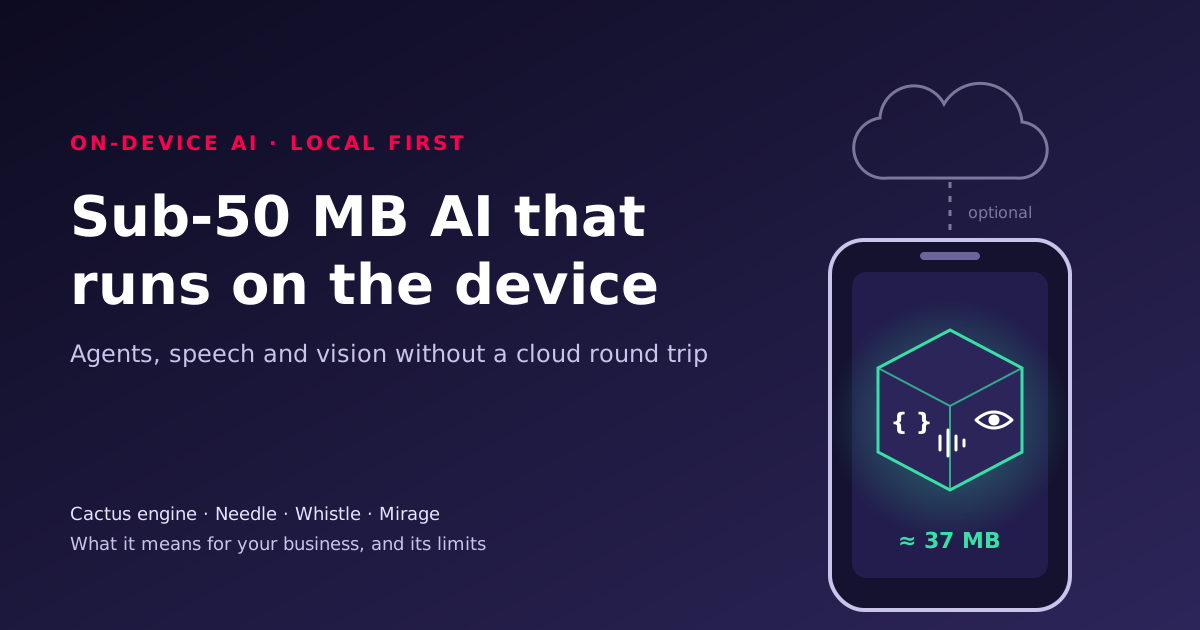
Sub-50 MB On-Device AI: What Cactus's Engine Means for Business
Cactus Compute's open-source engine (not NVIDIA's, as first reported) runs tool calling, speech and vision models under 50 MB each on phones and laptops. What it is, what we measured, its limits, and which AI tasks belong on the device.
Aus der Halle der GTC Berlin: Huang sagt, KI ist jetzt produktiv
Workstation-Ingenieure waren am 21. Oktober 2026 zur Keynote in der STATION-Berlin. Huangs Wende führte von Fabriken zu Agenten, die Tokens verbrauchen.
 Balinder WaliaLesen
OpenShell, vorgestellt auf der GTC Berlin: Richtlinien außerhalb des Agenten
Huangs Sicherheitsfilm verwarf „Bitte nicht“ als Kontrollmechanismus. OpenShell setzt eine Richtlinie für Systemaufrufe, Dateien und Netzwerk durch, mit Sentry auf BlueField-4.
Balinder WaliaLesen 
Die Berliner Folie, die Dokumente von Datenbanken trennt
Nemotron Parse, Embed, cuVS und Rerank in einer Reihe. Auto-Ontology, cuDF und Kumo in der anderen. Huangs Beispiel mit dem Lieferverzug nutzt beide.
Balinder WaliaLesen 
NVIDIA Minerva für KI-Fabriken: Aus Alarmstürmen werden zurückgewonnene GPU-Stunden
Eine einzige nachlassende Optik kann Tausende von Alarmen auslösen und tausend GPUs ausbremsen. Was NVIDIA Minerva leistet, was es in GPU-Stunden, Goodput, MTBI, MTTR und Tokens wert ist, welches seiner drei Nutzungsmodelle passt, durchgerechnete Beispiele für eine Neocloud mit Vera Rubin NVL72, einen Blackwell-Cluster an einer Universität und ein Unternehmen mit Grafana und ServiceNow sowie das Verhältnis zu UFM.
Balinder WaliaLesen 
KI-Agenten mit NebulaDB bauen: semantische Suche, RAG und ein Visa-KI-Agent
Wie wir semantische Suche, RAG und einen KI-Agenten für thailändische Visa auf NebulaDB gebaut haben, mit echten Abfragen, Abfrageplänen und Retrieval-Werten, gemessen auf unserem Produktionsserver mit 8,3 Millionen Dokumenten, und die Schutzmechanismen, die private Daten und erfundene Zahlen aus den Antworten heraushalten.
Balinder WaliaLesen 
TuneBench: How Well Can AI Agents Calibrate Power System Models?
TuneBench tests LLM agents on calibrating generator and battery models within 15 simulations. Only Opus 5.5 and GPT-6 hit median R² above 0.995 in every test. What that figure means, its limits, and how to build the same kind of benchmark.
Agentic AI in banking: efficiency you can defend to a risk committee
Banking AI agents rarely fail on one bad reply; they fail across a session. How to scope tools, test whole conversations against mock systems and measure reliability with pass^k, so the time saved survives audit and production.
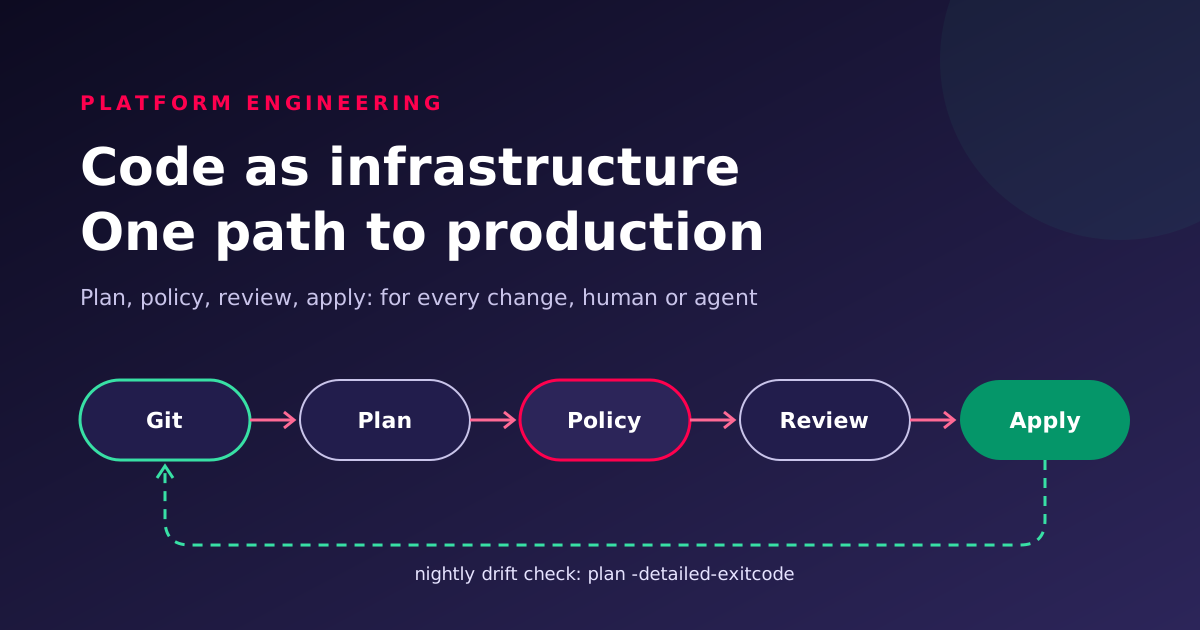
Code as infrastructure: one reviewed path for every production change
Infrastructure as code made servers into files. Code as infrastructure goes further: desired state, policy, pipelines and AI agent access all live in Git, are checked by policy, applied by automation and watched for drift. A practical playbook.