Der Shop ist online

Wir bauen Workstation AI-Maschinen für Websites, KI-Agenten und LLM-Training – online konfigurieren und kaufen.

Händlerpreise erhalten
KI-Produkte
KI-LabsOpenAI-AgentenClaude-AgentenGrok-BotWorkstation AI-natives CRMMarketingAlle Produkte
KI-Lösungen
Angewandte KIKI-AgentenGenerative KIKI-AutomatisierungKI-WeiterbildungKI-Pakete für KMUEnterprise AI LabKI-WorkstationsNVIDIA-Hardware & -SoftwareNVIDIA Accelerated ComputingPrivate KIGPU-Private-CloudGPU-ClusterEdge-KIKI nach Branche
KI-Services
PlattformmodernisierungDigital EngineeringDatengrundlagen & KIAutonomer BetriebKI-BeratungDevOps-AutomatisierungCybersicherheitSoftwareentwicklungAgentenentwicklungMLOps-EinrichtungGPU-LeasingGPU-Private-Cloud
Über uns
UnternehmenUnsere GeschichtePartnerKundengeschichten
KI-Rechenzentren
KI-RechenzentrenGPU-Private-CloudGPU-ClusterGPU-Leasing
KI-EinblickeJev-ReiheBenchmark LabModellauswahl
Technische Hinweise
Dokumentation
Linux-BetriebssystemeUbuntuRed Hat Enterprise LinuxSUSE LinuxAlpine LinuxDebian, Rocky & AlmaLinux
KI-Cloud-PlattformenAWS & Amazon BedrockGoogle Cloud & Vertex AIMicrosoft Azure & AI FoundryGPU-Clouds & Marktplätze
Private KI-RechenzentrenFür AnwaltskanzleienFür Steuer- und WirtschaftsprüfungskanzleienOn-Premises-PlattformenVollständig abgesicherte Cloud
ToolsRing PromoterJobshout
News
Blog
KontaktAnmelden

KI-Workstations, Multi-Agenten-KI-Software, GPU-Infrastruktur und intelligente Agentenlösungen für moderne Unternehmen.

Kontakt

KI-Lösungen

Angewandte KIKI-AgentenGenerative KIKI-AutomatisierungKI-WeiterbildungKI-Pakete für KMUEnterprise AI LabKI nach Branche

Produkte

Alle ProdukteWorkstation AI-natives CRM & ERPMarketingOpenAI-AgentenRing PromoterJobshout

Unternehmen

Über unsUnternehmenKI-RechenzentrenWarum WorkstationPartnerKundengeschichtenPreiseKontaktTenthMatrix

Ressourcen

KI-EinblickeTechnische HinweiseDokumentationLinux-BetriebssystemeKI-Cloud-PlattformenPrivate KI-RechenzentrenBlogSucheSitemap
Büro Belgien
Workstation SRL, Rue Vanderkindere 34, 1180 Uccle, BrusselsBE 0751.518.683Mo – Fr: 9:00 – 18:00 Uhr MEZ
+32 492 45 67 46
Hauptsitz Großbritannien
77-79 Marlowes, Hemel Hempstead HP1 1LFAnfahrt – Ausfahrt 20 der M25 (Outer London)Handelsregisternr.: 11641870Mo – Fr: 9:00 – 18:00 Uhr GMT
+44 7515 356 146
Büro Indien
#159 Sector 9, Pocket 1, DDA Flats, 110077 Dwarka, New Delhi
+91 98881 98841
Büro Taiwan
3F, No. 2-4, Aisi Rd., Ren'ai Dist., Keelung City 200, Taiwan基隆市仁愛區愛四路2之4號3樓Mo – Fr: 9:00 – 18:00 Uhr Taiwan-Zeit (GMT+8)
+886 926 892 701+32 492 45 67 46
Büro Estland
Aleksander Puškini tn 30-25, 20306 Narva, EstoniaMo - Fr: 9:00 - 18:00 Uhr estnischer Zeit (EET)
+32 492 45 67 46

© 2026 Workstation AI. Alle Rechte vorbehalten.

DatenschutzDatenlöschungCookiesNutzungsbedingungenWebsite-Sitemap

NVIDIA, das NVIDIA-Logo, RTX, RTX PRO, Blackwell, CUDA, NVLink, MGX, Omniverse, Spectrum-X, Quantum, BlueField, DGX und HGX sind Marken und/oder eingetragene Marken der NVIDIA Corporation in den USA und anderen Ländern. AMD, das AMD-Arrow-Logo, EPYC, Instinct, Ryzen und Threadripper sind Marken von Advanced Micro Devices, Inc. Dell und PowerEdge sind Marken der Dell Inc. oder ihrer Tochtergesellschaften. Intel und Xeon sind Marken der Intel Corporation oder ihrer Tochtergesellschaften. AMAX, AceleMax und LiquidMax sind Marken der AMAX Engineering Corporation. Alle anderen Produktnamen, Logos und Marken sind Eigentum ihrer jeweiligen Inhaber. Wir verwenden sie ausschließlich, um die Produkte zu kennzeichnen, die wir beschreiben, liefern oder unterstützen; ihre Verwendung bedeutet nicht, dass ihre Inhaber uns empfehlen.

Loading blog...

Startseite / Blogs
AIAmdData CentreGPUNvidia

Chipping Away at Nvidia's Lead: Lisa Su's AMD Plan, Two Years On

Workstation14. November 20264 min read
79f02641 8b11 4fbd babc e97a18613314

In December 2024, Bloomberg's Emily Chang visited AMD's labs in Austin to ask Lisa Su, ten years into her time as CEO, how she planned to chip away at Nvidia's lead in AI. Almost two years on, AMD's own results let us check the plan against what happened, and ask what it means for UK organisations buying AI infrastructure today.

Watch the interview. AMD's CEO Wants to Chip Away at Nvidia's Lead | The Circuit with Emily Chang (Bloomberg Originals, 24 minutes, published 6 December 2024).

What Lisa Su said

The episode is part company profile, part race story, and Su's lines are worth hearing in full. The points that matter for anyone buying AI hardware:

  • The pace. She called AI "the most transformational technology that I've seen in my career", ahead of the internet, PCs, mobile and cloud, and said the industry had made more progress in the previous 18 months than in the ten years before.
  • The product. She showed the Instinct MI300, already in production and running work such as GPT-4o on Microsoft Azure and Meta's Llama models.
  • The underdog question. Asked whether being seen as the next-best option to Nvidia was good enough, she said AMD has always "punched well above our weight" in technology. Bloomberg's chip reporter Ian King described AMD as "a solid number two".
  • Custom chips. On hyperscalers designing their own silicon: "This is a huge market... There's like more than enough chips for everybody to build."
  • Export controls and supply. She accepted there is "a national security element" to limits on AI chip exports, while wanting "as open a market as possible", and stressed resilience in a supply chain concentrated in Taiwan.

The rest covers her ten years turning AMD around (the Zen architecture was "the most important moment"), the Mercedes Formula 1 partnership, a Porsche collection named after AMD products, and her advice to young engineers: "run towards problems".

Two years on: the scorecard
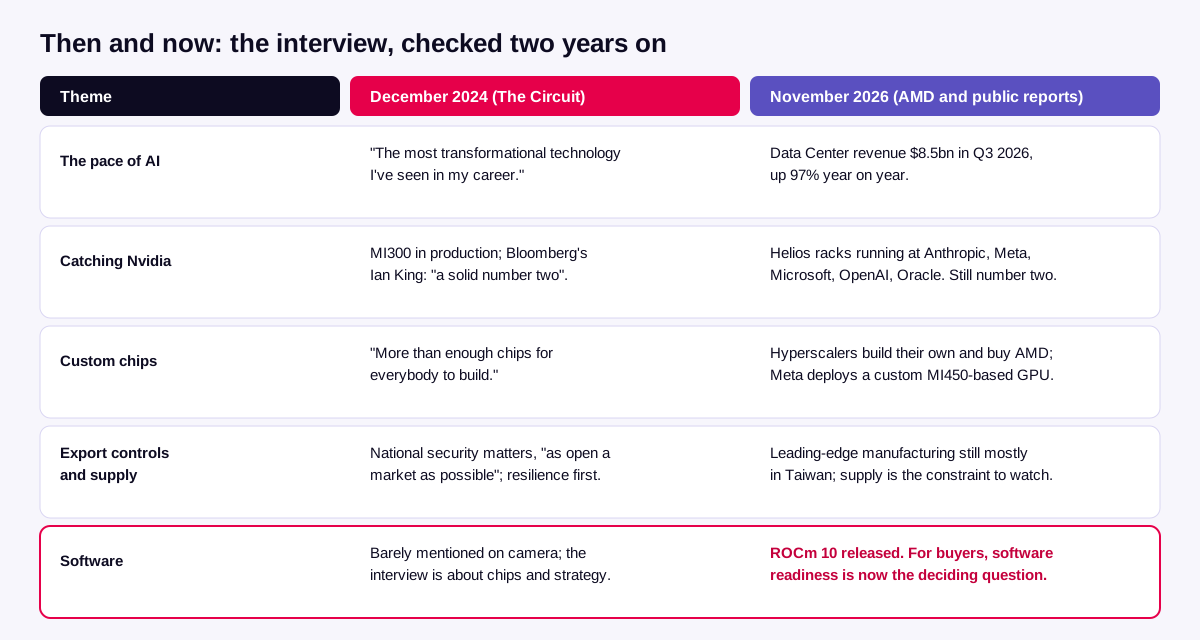
What Lisa Su said in December 2024, and what has happened since. Five themes from the interview checked against November 2026. AI pace: she called AI the most transformational technology of her career; AMD's Data Center revenue has nearly doubled year on year. Competing with Nvidia: Bloomberg called AMD a solid number two; Helios now ships to five of the largest AI buyers, though Nvidia remains far larger. Custom chips: she said there are more than enough chips for everybody; hyperscalers build their own and also buy AMD, and Meta is deploying a custom MI450-based GPU. Supply resilience and export controls: she backed national-security controls with as open a market as possible, and stressed supply-chain resilience; manufacturing is still concentrated in Taiwan. Software: not covered in depth on camera; ROCm 10 is now the deciding factor for most buyers.
Five themes from the December 2024 interview checked against November 2026. Sources: the Bloomberg Originals episode and AMD's third-quarter 2026 results.

AMD's third-quarter 2026 results, published on 3 November, are the clearest check. Data Center revenue reached a record $8.5bn, up 97% year on year, driven by EPYC server processors and the launch of the Instinct MI450 Series. Anthropic, Meta, Microsoft, OpenAI and Oracle Cloud Infrastructure are running models on the first Helios racks, AMD's answer to Nvidia's rack-scale systems. AMD expects around $17bn of total revenue in the fourth quarter.
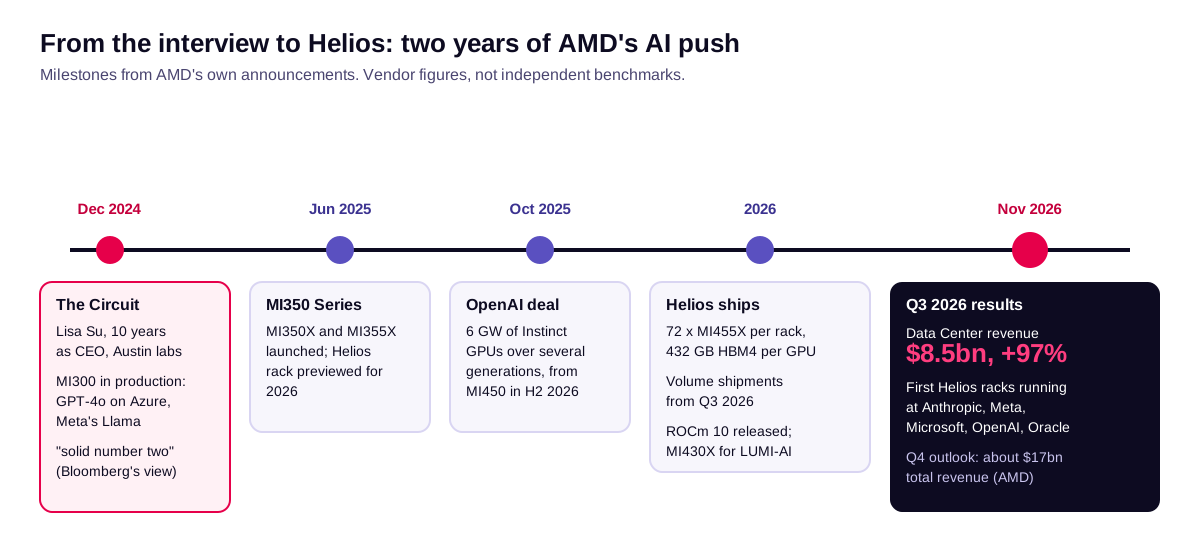
AMD's AI data-centre push, December 2024 to November 2026. A timeline. December 2024: Lisa Su on Bloomberg's The Circuit, ten years as CEO, with the Instinct MI300 in production and running GPT-4o on Microsoft Azure and Meta's Llama. June 2025: Instinct MI350 Series launched. October 2025: multi-year agreement with OpenAI for 6 gigawatts of Instinct GPUs. 2026: Helios rack-scale system with 72 Instinct MI455X GPUs enters production and ships in volume in the third quarter; ROCm 10 released. November 2026: third-quarter Data Center revenue a record 8.5 billion dollars, up 97 percent year on year, with Anthropic, Meta, Microsoft, OpenAI and Oracle running workloads on the first Helios racks.
From the interview to Helios: MI350 in June 2025, the OpenAI agreement in October 2025, Helios shipping in volume from the third quarter of 2026. Milestones from AMD's announcements.

Helios packs 72 Instinct MI455X GPUs into one rack, each with 432 GB of the newest HBM4 memory, for 31 TB per rack. AMD claims it beats Nvidia's Vera Rubin NVL72 on compute, memory and tokens per dollar. Those are AMD's numbers, and Nvidia remains far larger, with the deeper software ecosystem. But "solid number two" now means a second full platform that the biggest AI companies run in production, not a niche alternative.

What it means if you are buying AI infrastructure in the UK

  1. You have a real choice. For many workloads, especially serving large language models with long contexts, AMD's larger memory per GPU can mean fewer GPUs per model. That is worth testing, not assuming.
  2. Software is the deciding question. Code written in PyTorch, or served with vLLM or SGLang, usually runs on AMD's ROCm software with little change. Custom CUDA code and Nvidia-only tools are where the work is.
  3. Two vendors give you leverage. Teams that can run on both negotiate better prices and are less exposed when one vendor's lead times stretch.
  4. Supply risk has not gone away. As Su said, the industry depends on a concentrated supply chain. Plan lead times into AI projects whichever vendor you choose.
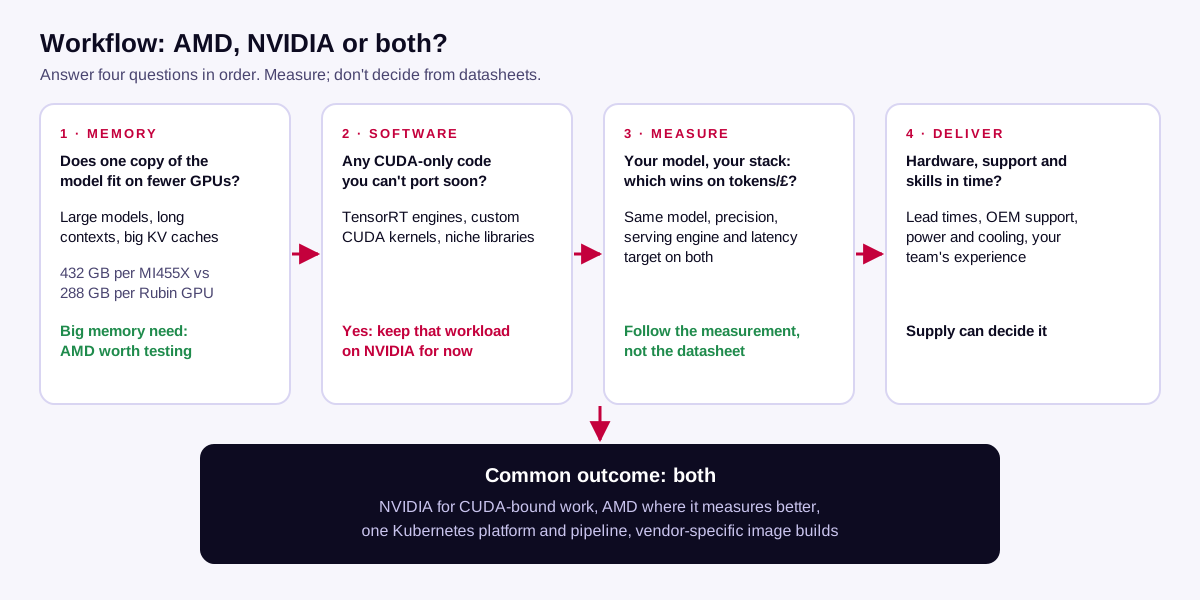
Workflow: choosing AMD, NVIDIA or both for an AI project. Four questions in sequence. Does the model need more memory per GPU than you can comfortably get, for example very large models or long contexts? If so, AMD's 432 GB per GPU can reduce how many GPUs each copy of the model needs. Does your software depend on CUDA-only libraries or custom kernels you cannot port soon? If so, stay on NVIDIA for that workload. Does a benchmark of your own model, on your own serving stack, show better tokens per pound on one vendor? Follow the measurement, not the datasheet. Can you get the hardware, support and skills in time? Supply, lead times and your team's experience can decide it. Many organisations end with both: NVIDIA for CUDA-bound work and AMD where it measures better.
Four questions to decide between AMD, Nvidia or both: memory, software dependencies, a benchmark on your own model, and whether hardware and skills arrive in time.

For the full engineering detail, with the platforms compared layer by layer, memory arithmetic, the CUDA-to-ROCm software map, a porting workflow with commands, running both vendors on one Kubernetes platform and a fair benchmarking method, read our technote: AMD Instinct vs NVIDIA for AI infrastructure: evaluate, port and run both.

How Workstation helps

We design and run GPU infrastructure for UK organisations and help teams evaluate AMD alongside Nvidia: a like-for-like benchmark of your own model on both, a check of your code for CUDA-only dependencies, and a Kubernetes platform that runs either. See our GPU private cloud guide, which includes AMD's official Helios video, compare leasing and buying at gpuleasing.co.uk, or talk to us.

Quotes are from the Bloomberg Originals video. Company figures are from AMD's announcements and are vendor claims, not independent benchmarks. This post is independent and not endorsed by Bloomberg, AMD or Nvidia.

Acknowledgement of rights: AMD, Instinct, EPYC, ROCm, Helios and Zen are trademarks of Advanced Micro Devices, Inc. NVIDIA and Vera Rubin are trademarks of NVIDIA Corporation. Bloomberg is a trademark of Bloomberg Finance L.P. Other names are the property of their respective owners.