Der Workstation-Blog
LLM
Beiträge mit dem Tag LLM.
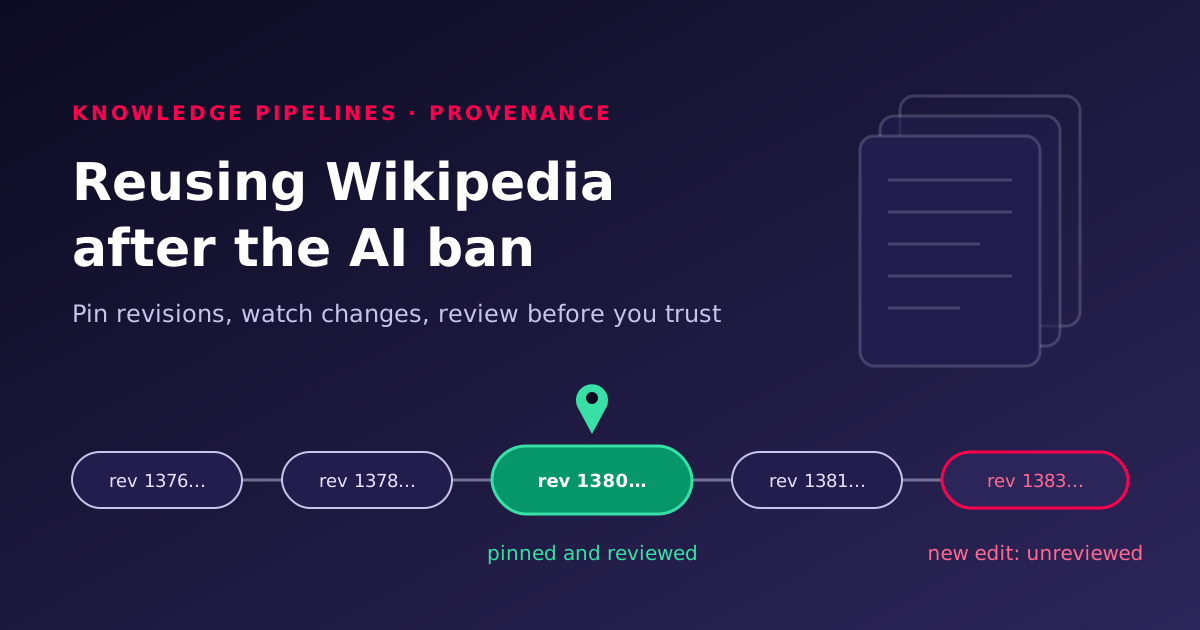
Wikipedia banned AI-written articles: what teams that reuse it should change
English Wikipedia now prohibits LLM-written article text, yet volunteers still flag a steady share of new drafts as AI-generated. If your search, chatbot or knowledge base reuses Wikipedia, here is how to pin revisions, watch edits, review changes and attribute correctly.
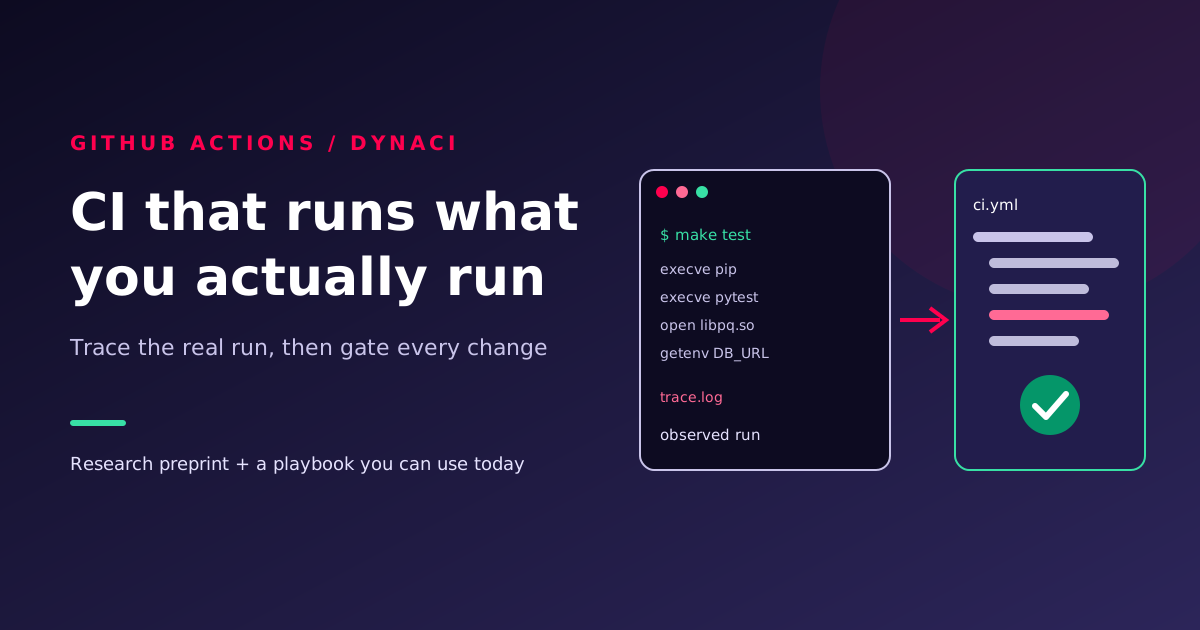
DynaCI and runtime-grounded CI: better GitHub Actions workflows
DynaCI, an October 2026 research preprint, drafts GitHub Actions workflows from traces of real local runs. What its results show, what they do not, and a playbook to lint, test, harden and review every workflow you ship.
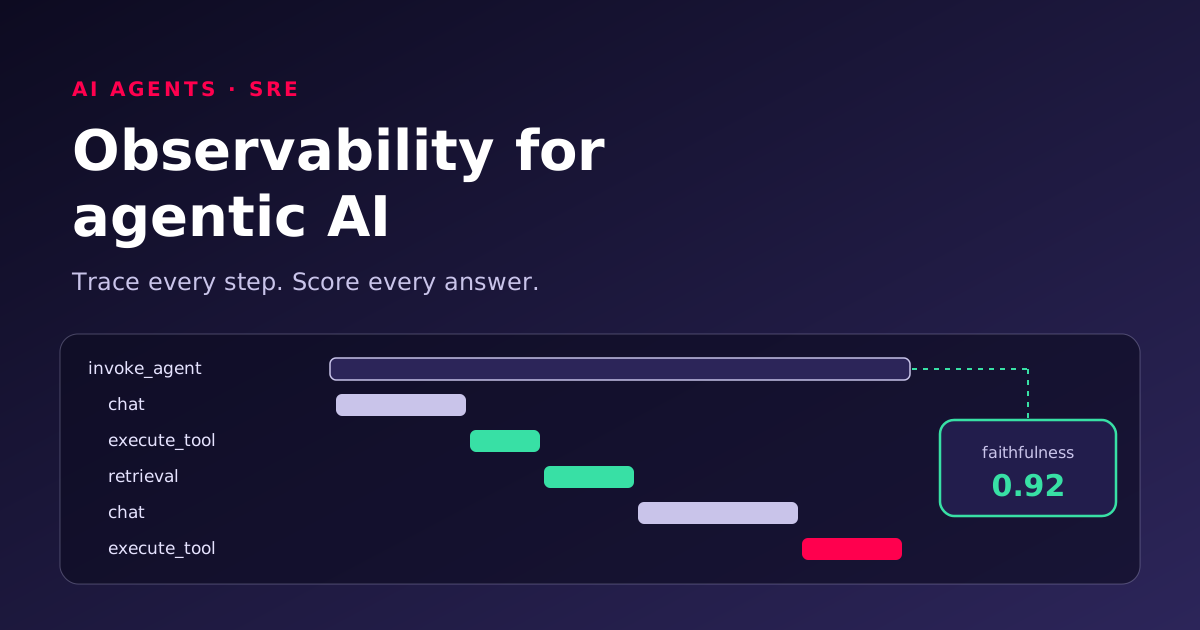
Observability for Agentic AI: Tracing, Evaluating and Auditing Agents
AI agents fail quietly: a confident answer from the wrong document, a tool called with the wrong argument. Learn how to trace every model, retrieval and tool step with OpenTelemetry, attach quality scores, and keep the records auditors ask for.
Trading costs with agents: what an AI agent really costs to run
AI agents move cost rather than remove it. Learn why the token bill grows with the square of loop steps, how caching and compaction bend the curve, and a playbook for pricing, budgeting and capping an agent before it reaches production.
The energy cost of LLM code optimisation, and when it pays back
A 2026 study found LLM-optimised code used more energy per run than the human reference in 42 of 44 configurations. Learn the break-even rule, how to measure joules per run on Linux, and a workflow for keeping only the rewrites that pay back.
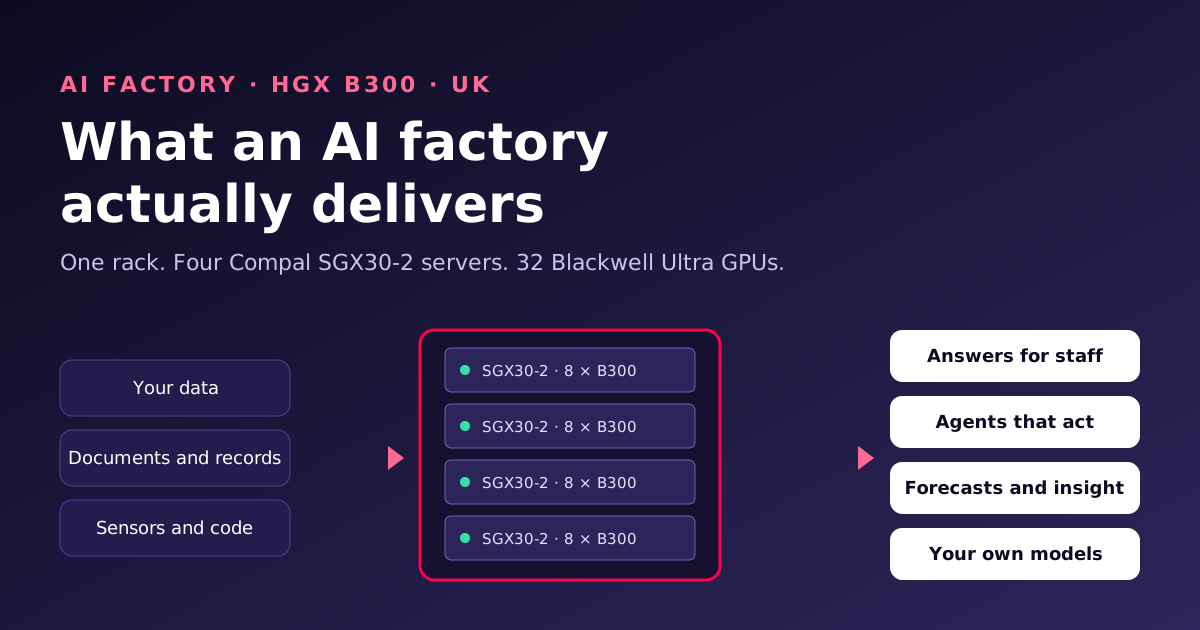
Was eine KI-Fabrik tatsächlich liefert: Ein Rack, 32 Blackwell Ultra GPUs und die Arbeit, die sie für Sie erledigt
Eine KI-Fabrik verwandelt Ihre eigenen Daten auf Hardware unter Ihrer Kontrolle in Antworten, Agenten, Prognosen und trainierte Modelle. Hier erfahren Sie, was hineingeht, was herauskommt, wie die Arbeit täglich abläuft und was ein Rack mit vier Compal SGX30-2 Servern und 32 NVIDIA Blackwell Ultra GPUs für den Betrieb benötigt.
 Balinder WaliaLesen
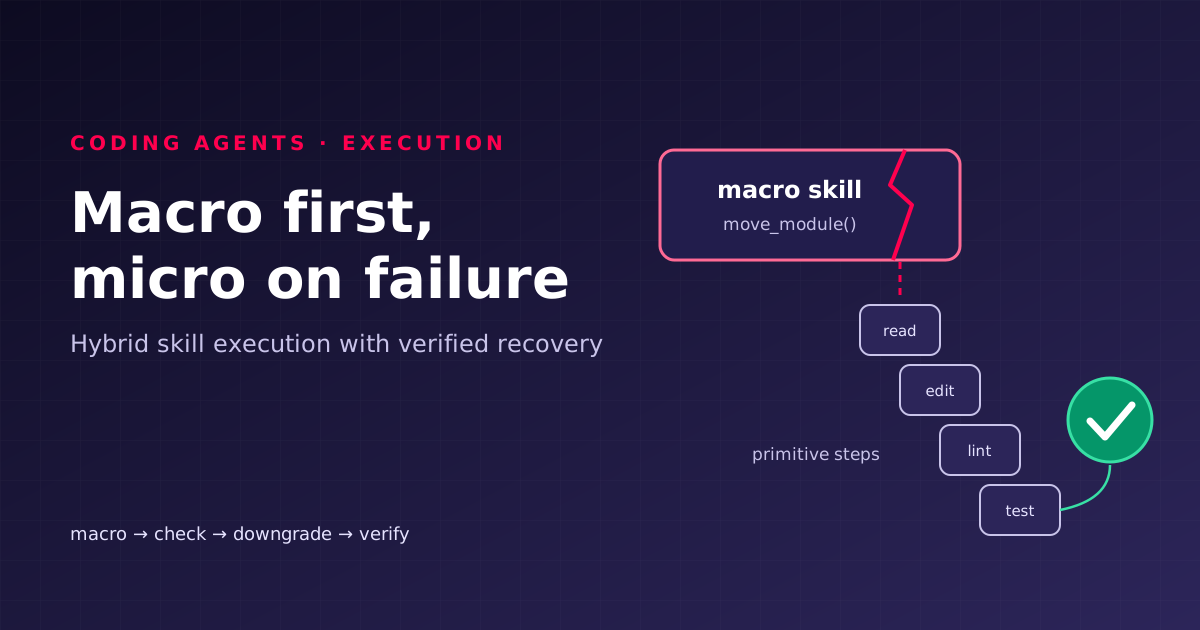
Hybrid Execution for Coding Agents: Macro Skills, Micro Recovery
Bundled macro skills make coding agents cheap but brittle; primitive tool calls make them robust but costly. Here is how to run macros first, verify every result, and fall back to small steps only when the workspace shows it is needed.
Generative AI's Hidden Impact on Developers: What Surveys Miss
Developers say AI makes them faster, but the evidence shows hidden costs: almost-right answers, a gap between felt and measured speed, tool admin work and accessibility barriers. Here is what the research says and how to measure it in your team.
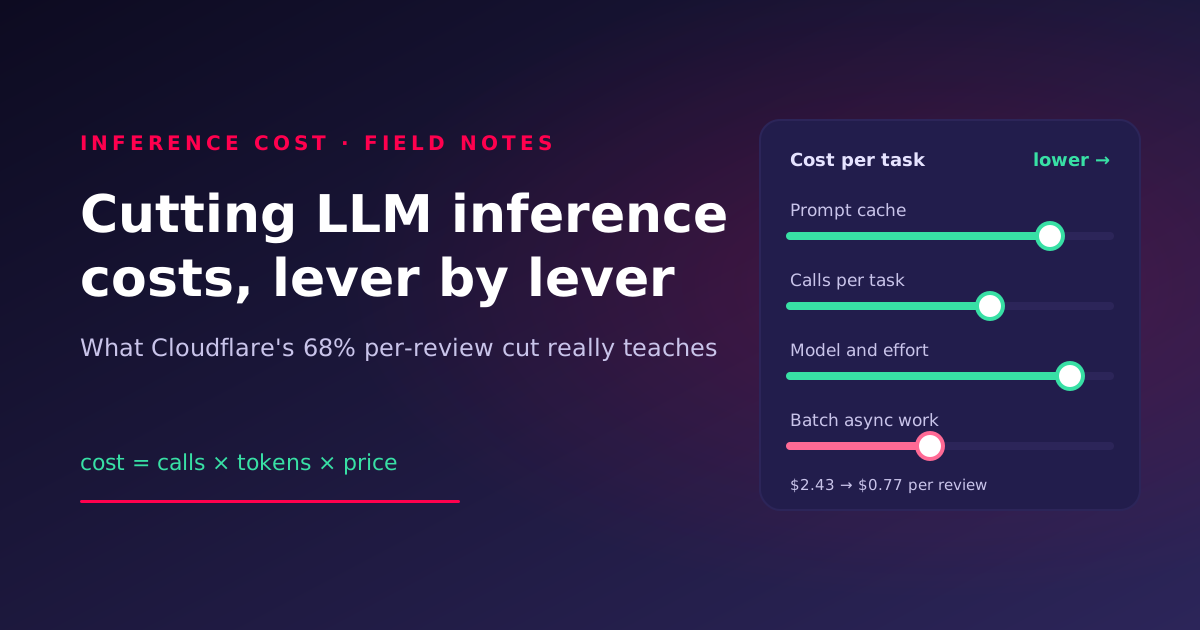
Cutting LLM Inference Costs: Lessons from Cloudflare's 68% Cut
Cloudflare cut its AI code reviewer's average cost per review by 68%. Here is what that number does and does not mean, and a measured playbook for your own workload: prompt cache breakpoints, fewer agent calls, right-sized models and batch.