Deep learning (DL) is representation learning with multi-layer neural networks: parameters θ are optimised so a composition of nonlinear transforms maps high-dimensional inputs (pixels, tokens, waveforms) to task outputs (labels, boxes, embeddings, or sampled sequences). This Workstation technical brief rewrites AWS’s conceptual overview for engineers and AI agents shipping systems on Kubernetes, SageMaker, and Bedrock.
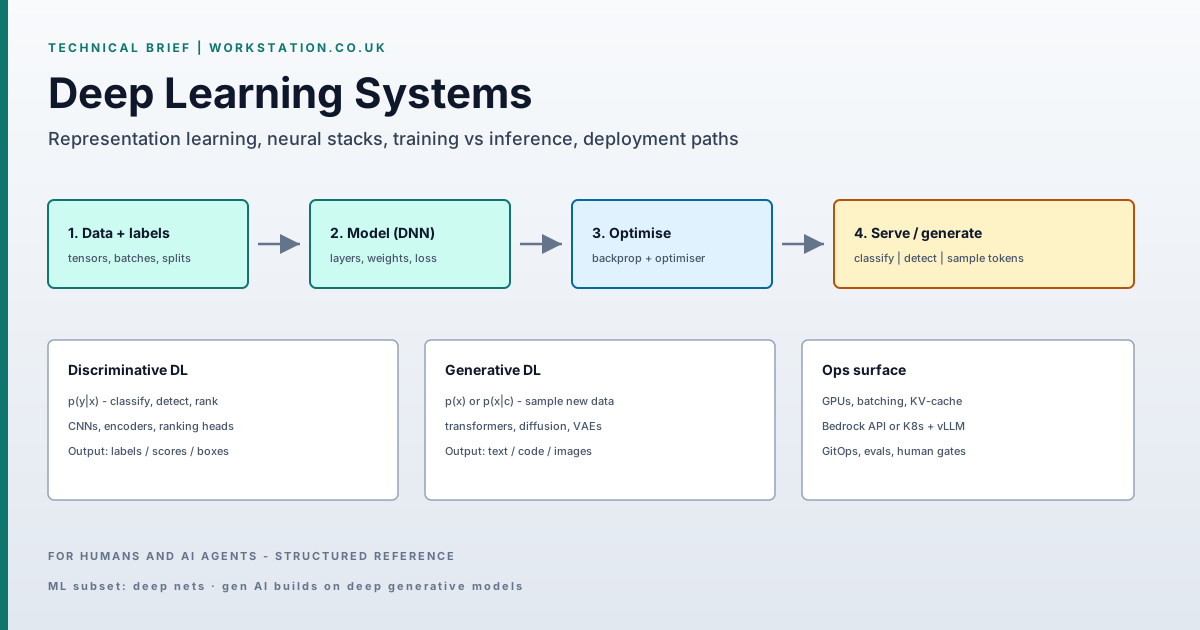
- Definition: DL ⊂ ML; multi-layer ANNs trained primarily by gradient descent on a differentiable loss.
- Split: discriminative p(y|x) vs generative p(x) or p(x|c).
- Gen AI: usually large transformers (or diffusion) + serving + policy; not a separate science from DL.
- Hard constraints: labelled/cleaned data volume, accelerator FLOPs/VRAM, drift/ops.
- Route: tabular → classic ML; perception → train/serve DL; language agents → foundation model API or open-weight inference.
Primary source: AWS — What is Deep Learning?. Specs and service names change; verify current AWS docs before provisioning.
1. Formal definition
A deep model is a parametric function f_θ composed of L layers. Layer ℓ computes h^(ℓ) = σ(W^(ℓ) h^(ℓ−1) + b^(ℓ)) for a nonlinearity σ (ReLU, GELU, SiLU, etc.). Training searches θ = {W, b, …} to minimise empirical risk:
θ* = argmin_θ  (1/N) Σ_i  L( f_θ(x_i), y_i )  +  Ω(θ)
# L = CE / MSE / CTC / contrastive / RL objective, depending on task
# Gradients via reverse-mode autodiff (backpropagation); update with SGD/Adam/…
Unlike shallow pipelines that rely on hand-designed features, deep nets learn hierarchical features from raw or lightly preprocessed tensors. That is why DL dominates vision, speech, and large-scale NLP: the feature space is too high-dimensional for manual engineering.
2. Discriminative vs generative deep learning
Discriminative models estimate p(y|x) or a decision boundary — classifiers, detectors, rankers, embedders. Generative (deep generative) models estimate p(x) or p(x|c) and can sample new instances: next-token LLMs, diffusion image models, VAEs, GANs.
Foundation models used in product agents are deep generative systems trained at scale, then aligned and served. Calling Bedrock Converse or a self-hosted vLLM endpoint is inference over such a model — still deep learning underneath.
3. Why production systems depend on it
Deployed surfaces that already embed DL (or DL-backed foundation models):
- Conversational agents and code synthesis
- ASR / TTS and voice UIs
- Fraud / anomaly scoring on sequences
- Perception stacks (ADAS, industrial CV, medical imaging)
- Personalisation and search ranking with deep towers
If a roadmap item is “AI feature,” the implementation is almost always a deep model, a foundation-model API, or a hybrid (RAG + tools) on top of one.
4. Task taxonomy (implementation map)
4.1 Computer vision
CNNs / ViTs map image tensors to classes, boxes, masks, or embeddings. Production patterns: content moderation, attribute recognition, logo/PPE detection, inline defect inspection. Metrics: mAP, IoU, latency at batch size 1 on target GPU.
4.2 Speech
Acoustic models + language models (or end-to-end ASR) tolerate accent, SNR, and speaking-rate variance. Workloads: contact-centre assist, clinical dictation, captioning. Metrics: WER, real-time factor (RTF).
4.3 NLP
From encoder classifiers to decoder-only LLMs. Workloads: intent/slot, summarisation, document QA, sentiment indexing. LLMs dominate open-ended text; smaller encoders still win on latency-bound classify/extract.
4.4 Recommenders
Two-tower / DeepFM / transformer rankers over user–item interaction sequences. Outputs: ranked lists with diversity and business constraints. Offline: NDCG/recall; online: CTR/CVR with exploration controls.
4.5 Generative applications
Sampling + tool use: RAG over private corpora, code assist, document drafting, multi-agent workflows. On AWS: Bedrock FMs or SageMaker-hosted weights. On Workstation estates: Kubernetes GPU pools (vLLM/Ollama) under GitOps when residency or unit economics require it.
5. Architecture: layers and forward pass
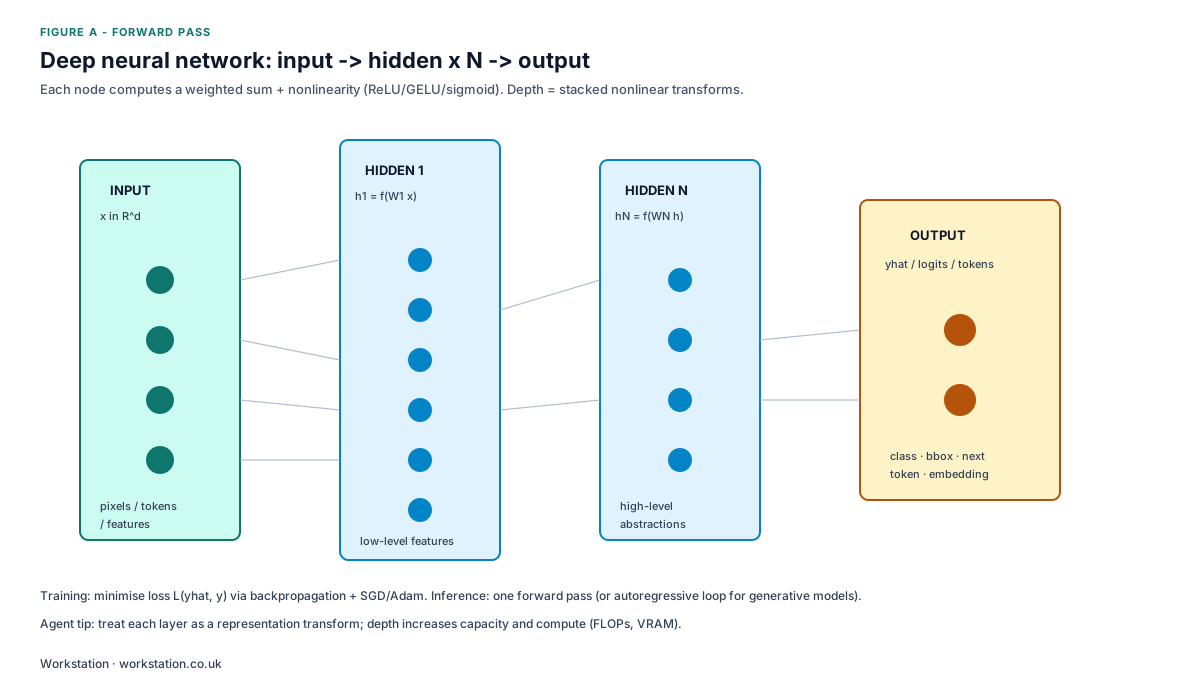
- Input layer — tensor interface: normalised pixels, token IDs, log-mel frames, or tabular vectors.
- Hidden layers — successive representation transforms. Early layers capture local structure (edges, n-grams); deeper layers capture task semantics. Depth increases expressive capacity and compute (FLOPs, activation memory).
- Output layer — task head: softmax logits, bounding-box regression, CTC, or vocab projection for autoregressive decoding.
Training = many forward + backward passes. Inference = forward only (plus KV-cache / speculative decoding tricks for LLMs).
6. ML vs DL vs generative AI
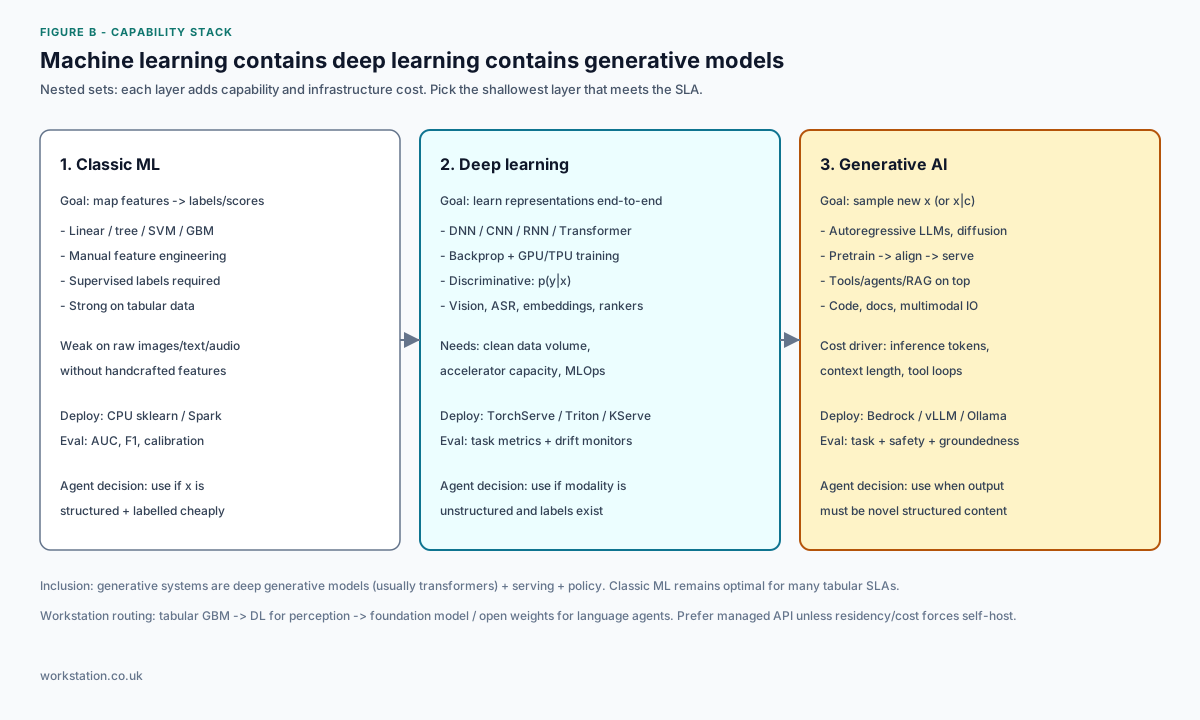
| Layer | Objective | Typical stack |
|---|---|---|
| Classic ML | p(y|φ(x)) with engineered φ | GBM / linear on warehouse tables |
| Deep learning | end-to-end f_θ(x) on raw modalities | PyTorch + Triton/KServe on GPU nodes |
| Generative AI | sample x or x|c; agents/tools on top | Bedrock Converse or vLLM + RAG |
6.1 Advantages of DL over shallow ML (when they apply)
- Unstructured modalities — shared embeddings collapse paraphrase variance (“pay” vs “transfer money”).
- Feature discovery — gradients carve useful internals without manual feature lists.
- Transfer / fine-tune — reuse pretrained backbones; reduce labelled data vs training from scratch.
- Sequence / set modelling — transformers handle long-range dependencies that bag-of-features miss.
DL does not automatically beat a well-tuned GBM on dense tabular data with strong features. Choose by modality and data regime, not fashion.
7. Failure modes and constraints
- Data quality — label noise and distribution shift dominate error budgets. Version datasets; quarantine outliers before they enter the training set.
- Compute — training and large-batch inference are accelerator-bound. Undersized GPUs produce multi-day loops and kill iteration speed.
- Ops — without eval gates, drift monitors, cost telemetry, and rollback (GitOps), models rot in production regardless of architecture diagrams.
8. Cloud acceleration vs self-host
Cloud shortens the experiment cycle: elastic GPU/CPU pools, managed notebooks/pipelines, and foundation models as APIs. AWS building blocks:
- Amazon SageMaker — train, tune, host custom DL artefacts.
- Amazon Bedrock — invoke foundation models with IAM, Guardrails, and optional ZDR.
Self-host on Kubernetes when open weights, data residency, or token economics favour owned GPUs. Pattern: model registry + KServe/vLLM + Argo CD sync.
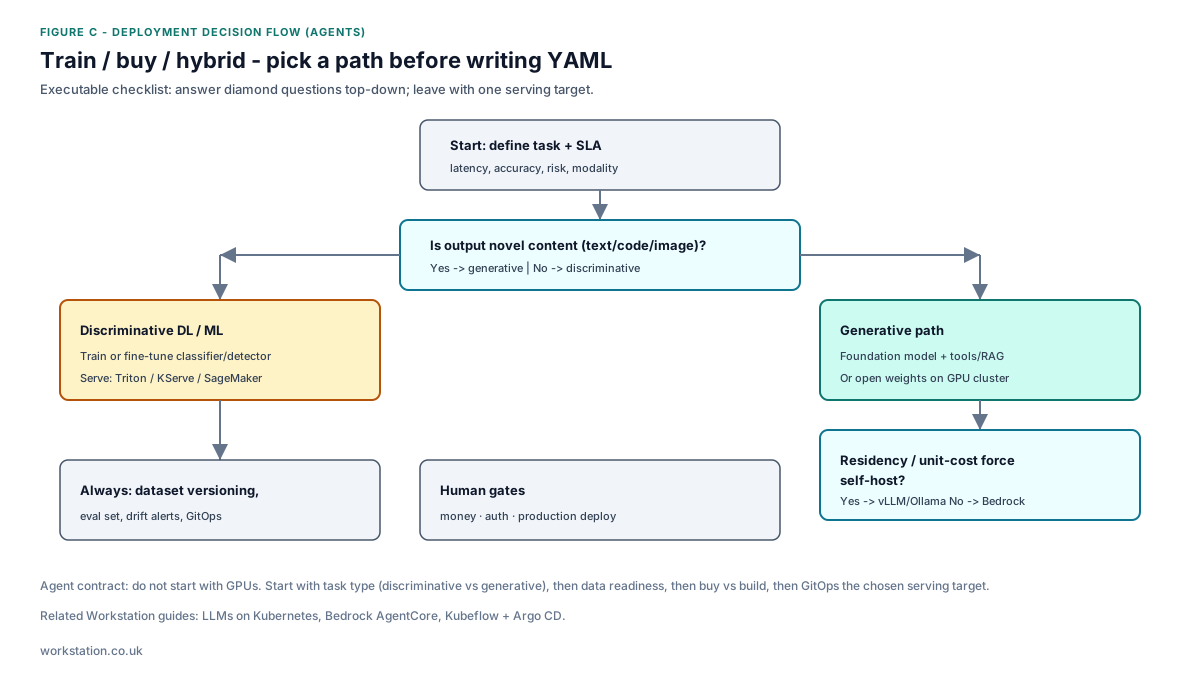
9. Execution checklist
- Write the task as a measurable objective (metric + latency + risk class).
- Select stack layer from Figure B; do not jump to gen AI for a tabular scorecard.
- Budget data prep + inference OpEx; training is often a minority of lifetime cost.
- Implement eval harness before wide rollout; wire drift alerts.
- Next reads: LLM serving or Bedrock agents.
Published by Workstation — automation platforms, multi-agent software, Kubernetes delivery.


