Moonshot AI’s Kimi K3 did not invent open weights — Llama, DeepSeek, Qwen, and others already proved the category. What changed in late July 2026 is that an open-weight model at ~2.8 trillion parameters, with a 1M-token context and day-0 production serving, is now competing on agent workloads that used to be reserved for Anthropic and OpenAI. This Workstation guide is for developers and technology leaders who need to decide: self-host, managed API, or hybrid — and which other open models belong on the radar.
1. What Moonshot shipped
According to Moonshot’s GitHub and technical materials (weights public ~27 Jul 2026):
- Kimi K3 — open-weight, native multimodal agentic model; ~2.8T total parameters (MoE).
- Architecture highlights: Kimi Delta Attention (KDA), Attention Residuals (AttnRes), Stable LatentMoE; sparse expert activation (order of 16 of 896 experts / ~100B-class active params per token — confirm on the live model card).
- 1M-token context; vision + tool use + long-horizon coding/knowledge work.
- Weights: Hugging Face
moonshotai/Kimi-K3(commonly distributed in MXFP4; footprint on the order of ~1.4TB). - Inference engines day-0: vLLM, SGLang, TokenSpeed; hosted API at platform.kimi.ai.
License: Kimi K3 License — not a free-for-all SaaS permit. Enterprises and Model-as-a-Service providers should legal-review before productising (VentureBeat and independent write-ups flagged commercial thresholds). Open weights ≠ open for every business model.
2. Can it keep up with Anthropic and OpenAI?
Short answer for builders: on several agent-relevant benches, yes — close enough that the default should no longer be “closed only.”
Community and vendor evaluations circulating after launch placed K3 in the same band as leading proprietary models on SWE-bench Verified and LiveCodeBench-style suites, with tool-use competitive against Claude Sonnet and GPT-4o-class baselines. That is the milestone: open weights clearing the bar on agent tasks, not just MMLU trivia.
Caveats Workstation insists on:
- Benchmarks are harness-sensitive — run your golden set.
- p50 latency wins can hide p95/p99 pain on multi-tool agent chains.
- Closed labs still lead on some product polish, safety tooling, and support SLAs.
- Hybrid routing (open for private data + closed for peak-critical) remains the pragmatic architecture.
3. Why infrastructure moved in days, not months
The strategic shift is serving maturity:
- vLLM published day-0 production guidance: KDA-aware prefix caching, kernels for NVIDIA/AMD, prefill/decode disaggregation, speculative decoding (DSpark draft models), tool calling, structured output.
- Cloud inference engines and hyperscalers (including AWS SageMaker HyperPod / EKS recipes) published deploy paths the same week weights appeared.
- Result: choosing self-host vs managed is increasingly a config and FinOps decision, not a quarter-long research project — if you already have GPU capacity and MLOps muscle.
4. Hardware reality (do not skip)
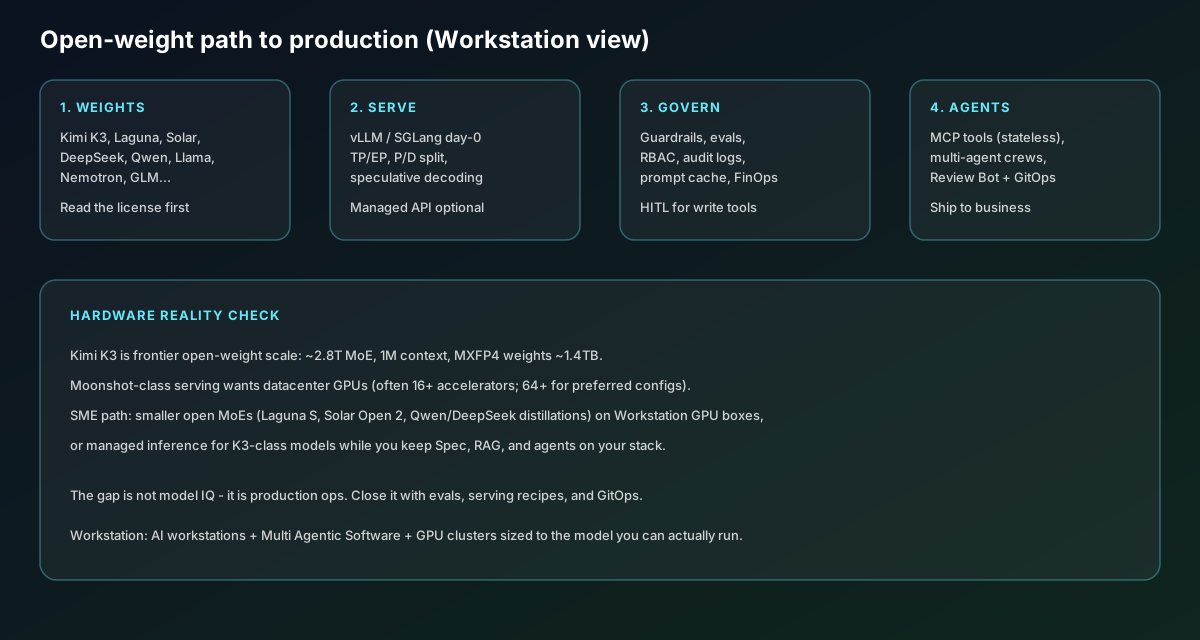
K3 is not a laptop model. Moonshot-oriented guidance points at datacenter-scale deployments (often 16+ high-end GPUs as a minimum credible path in published vLLM notes; preferred configs can run to 64+ accelerators). Weights alone are terabyte-class.
SME / mid-market path: run smaller open MoEs on Workstation AI boxes; call K3 via managed API when you need that IQ; keep RAG corpora and agents private.
Enterprise path: GPU cluster + vLLM/SGLang + GitOps + evals — or buy managed capacity and invest engineering in the agent layer instead of kernels.
Video: practical vLLM cloud serve walkthrough — useful before you size a K3-class node.
5. Policy and security backdrop
The same window saw NVIDIA and partners push the Open Secure AI Alliance and amplify the Open Weights and American AI Leadership letter (270+ orgs). The argument: open weights are not only an economics story — defenders need inspectable models to red-team agents and software supply chains. Pair openness with evals, guardrails, and rapid patch culture — not wishful “ban open models.”
6. MCP went stateless (why agents care)
The MCP 2026-07-28 specification is the largest protocol revision since launch:
- Removes initialize handshake and
Mcp-Session-Id— requests carry version/capabilities in_meta. - Any instance behind a plain load balancer can serve any request (no sticky Redis session tax).
- Hardened auth alignment with OAuth/OIDC; formal ~12-month deprecation policy.
- Extensions: MCP Apps (server-rendered UIs), MCP Tasks (durable long-running job handles).
For Workstation multi-agent stacks, stateless MCP means tool fleets scale like normal HTTP microservices — the missing piece when open models finally get agent-grade IQ.
7. The production gap (still the real story)
Industry surveys (including Mozilla’s open-source AI reporting) keep repeating a pattern: developers try open weights at high rates, but a smaller share reach production than closed-API teams — and the gap often widens with company size. Closed vendors sell a paved road; open models still require you to own serving, scaling, observability, and security. Kimi K3 raises the ceiling; it does not delete the ops half of the job.
8. Models on our radar (expanded)
Beyond K3, Workstation is watching this open / semi-open set for agentic coding and private AI stacks (verify licenses and benches before procurement):
| Model | Why it matters | Fit |
|---|---|---|
| Kimi K3 (Moonshot) | 2.8T MoE, 1M ctx, frontier open agent coding | Cluster / managed API |
| Laguna S 2.1 (Poolside) | 118B-A8B MoE, 1M ctx, strong Terminal/SWE benches, OpenMDW | Self-host SWE agents |
| Solar Open 2 (Upstage) | 250B-A15B, 1M ctx, agentic office/coding, KR sovereign angle | 4–8× H200 class |
| DeepSeek-V4 family | Continued open MoE pressure on reasoning/coding price-performance | Cost-sensitive agents |
| Qwen 3.x / Max (Alibaba) | Broad multilingual + tool ecosystem; distillations for workstations | Default open stack |
| Llama 4 class (Meta) | Permissive ecosystem, huge fine-tune/community tooling | Fine-tunes / RAG |
| Nemotron 3 (NVIDIA) | Open weights aligned with NVIDIA serving/security story | GPU-native estates |
| GLM-4.x / 5 (Zhipu) | Strong agent/tooling lineage; watch license + hosting region | Tool-heavy agents |
| KAT-Coder-V2.5 (Kwaipilot) | ~35B-A3B MoE coding specialist; Apache 2.0; SWE-bench sized | Workstation SWE |
| Mistral Large / Magistral | EU-friendly commercial open options; strong tooling story | EU private AI |
| Gemma 3 (Google) | Efficient open models for edge and on-device | Edge / Mac Silicon |
| Phi-4 class (Microsoft) | Small, capable reasoners for constrained boxes | SME workstations |
| Mage-Flow (Microsoft) | Compact ~4B text-to-image / edit; MIT; rival larger diffusion stacks | Local creative |
| Inflect v2 (Owen Song) | Tiny local English TTS (Nano/Micro); Apache 2.0 | Offline voice |
| Claude Opus 5 / Fable 5 (closed) | Still the quality ceiling for many coding/agent paths on Bedrock | Hybrid peak path |
| GPT-5.6 Sol/Terra/Luna (closed) | Tiered closed inference for router designs | Managed failover |
9. Practical patterns Workstation recommends
Private RAG + tools on open weights (Qwen / Laguna / Solar / DeepSeek)
        │
        ├─ Lead planner on K3 API or Opus 5 (Bedrock) when stuck
        ├─ Builders on mid open MoE self-hosted
        ├─ Review Bot + human gate
        └─ GitOps promote
- Write an ADR: default open model + failover closed model.
- Golden eval set (50–100 tasks) before flipping production.
- Measure p95/p99 on multi-tool agent chains — not median TTFT alone.
- Prompt-cache carefully (a UUID at the top of a prompt can nuke hit rates).
- Upgrade MCP servers to 2026-07-28 before you scale horizontally.
- Size GPUs to the model you will actually serve — not the blog headline.
10. Closing
Kimi K3 is a proof point: open weights now contest frontier agent work, and the serving ecosystem (vLLM, SGLang, cloud recipes) is keeping pace in days. Policy groups are arguing that open models are part of cyber defence, not only cost control. For businesses, the winning move is a hybrid router on Workstation-grade hardware and Multi Agentic Software — open where privacy and cost dominate, closed where quality SLAs demand it, with MCP, evals, and GitOps so “we tried an open model” becomes “we ship on open models.”
Published by Workstation. Specs and benches move weekly — re-check model cards, licenses, and region policy before you buy silicon.


