Der Shop ist online

Wir bauen Workstation AI-Maschinen für Websites, KI-Agenten und LLM-Training – online konfigurieren und kaufen.

Händlerpreise erhalten
KI-Produkte
KI-LabsOpenAI-AgentenClaude-AgentenGrok-BotWorkstation AI-natives CRMMarketingAlle Produkte
KI-Lösungen
Angewandte KIKI-AgentenGenerative KIKI-AutomatisierungKI-WeiterbildungKI-Pakete für KMUEnterprise AI LabKI-WorkstationsNVIDIA-Hardware & -SoftwareNVIDIA Accelerated ComputingPrivate KIGPU-Private-CloudGPU-ClusterEdge-KIKI nach Branche
KI-Services
PlattformmodernisierungDigital EngineeringDatengrundlagen & KIAutonomer BetriebKI-BeratungDevOps-AutomatisierungCybersicherheitSoftwareentwicklungAgentenentwicklungMLOps-EinrichtungGPU-LeasingGPU-Private-Cloud
Über uns
UnternehmenUnsere GeschichtePartnerKundengeschichten
KI-Rechenzentren
KI-RechenzentrenGPU-Private-CloudGPU-ClusterGPU-Leasing
KI-EinblickeJev-ReiheBenchmark LabModellauswahl
Technische Hinweise
Dokumentation
Linux-BetriebssystemeUbuntuRed Hat Enterprise LinuxSUSE LinuxAlpine LinuxDebian, Rocky & AlmaLinux
KI-Cloud-PlattformenAWS & Amazon BedrockGoogle Cloud & Vertex AIMicrosoft Azure & AI FoundryGPU-Clouds & Marktplätze
Private KI-RechenzentrenFür AnwaltskanzleienFür Steuer- und WirtschaftsprüfungskanzleienOn-Premises-PlattformenVollständig abgesicherte Cloud
ToolsRing PromoterJobshout
News
Blog
KontaktAnmelden

KI-Workstations, Multi-Agenten-KI-Software, GPU-Infrastruktur und intelligente Agentenlösungen für moderne Unternehmen.

Kontakt

KI-Lösungen

Angewandte KIKI-AgentenGenerative KIKI-AutomatisierungKI-WeiterbildungKI-Pakete für KMUEnterprise AI LabKI nach Branche

Produkte

Alle ProdukteWorkstation AI-natives CRM & ERPMarketingOpenAI-AgentenRing PromoterJobshout

Unternehmen

Über unsUnternehmenKI-RechenzentrenWarum WorkstationPartnerKundengeschichtenPreiseKontaktTenthMatrix

Ressourcen

KI-EinblickeTechnische HinweiseDokumentationLinux-BetriebssystemeKI-Cloud-PlattformenPrivate KI-RechenzentrenBlogSucheSitemap
Büro Belgien
Workstation SRL, Rue Vanderkindere 34, 1180 Uccle, BrusselsBE 0751.518.683Mo – Fr: 9:00 – 18:00 Uhr MEZ
+32 492 45 67 46
Hauptsitz Großbritannien
77-79 Marlowes, Hemel Hempstead HP1 1LFAnfahrt – Ausfahrt 20 der M25 (Outer London)Handelsregisternr.: 11641870Mo – Fr: 9:00 – 18:00 Uhr GMT
+44 7515 356 146
Büro Indien
#159 Sector 9, Pocket 1, DDA Flats, 110077 Dwarka, New Delhi
+91 98881 98841
Büro Taiwan
3F, No. 2-4, Aisi Rd., Ren'ai Dist., Keelung City 200, Taiwan基隆市仁愛區愛四路2之4號3樓Mo – Fr: 9:00 – 18:00 Uhr Taiwan-Zeit (GMT+8)
+886 926 892 701+32 492 45 67 46
Büro Estland
Aleksander Puškini tn 30-25, 20306 Narva, EstoniaMo - Fr: 9:00 - 18:00 Uhr estnischer Zeit (EET)
+32 492 45 67 46

© 2026 Workstation AI. Alle Rechte vorbehalten.

DatenschutzDatenlöschungCookiesNutzungsbedingungenWebsite-Sitemap

NVIDIA, das NVIDIA-Logo, RTX, RTX PRO, Blackwell, CUDA, NVLink, MGX, Omniverse, Spectrum-X, Quantum, BlueField, DGX und HGX sind Marken und/oder eingetragene Marken der NVIDIA Corporation in den USA und anderen Ländern. AMD, das AMD-Arrow-Logo, EPYC, Instinct, Ryzen und Threadripper sind Marken von Advanced Micro Devices, Inc. Dell und PowerEdge sind Marken der Dell Inc. oder ihrer Tochtergesellschaften. Intel und Xeon sind Marken der Intel Corporation oder ihrer Tochtergesellschaften. AMAX, AceleMax und LiquidMax sind Marken der AMAX Engineering Corporation. Alle anderen Produktnamen, Logos und Marken sind Eigentum ihrer jeweiligen Inhaber. Wir verwenden sie ausschließlich, um die Produkte zu kennzeichnen, die wir beschreiben, liefern oder unterstützen; ihre Verwendung bedeutet nicht, dass ihre Inhaber uns empfehlen.

Loading blog...

Startseite / Blogs
OllamaOpen WeightsLocal AIApple SiliconAI AgentsLLMAIMcp

Muse Glimmer on Ollama: Always-On Local Agents on One GPU

Meta’s 30B Apache 2.0 agent model — tool use, vision, failure recovery — and what it means for private AI on workstations

Balinder Walia12. August 20262 min read
Meta Muse Glimmer local agents on Ollama

Meta’s Muse Glimmer is a 30B open model tuned for always-on local agents — tool use, long tasks, failure recovery, vision — and it ships on Ollama under Apache 2.0 for a single GPU or Apple Silicon. Here is the Workstation business take. Specs, benches, methodology, and a production checklist in the long article.

Meta Muse Glimmer local agents on Ollama

Bottom line. Cloud frontier APIs still win on peak polish and managed SLAs. Muse Glimmer changes the default for private, always-on agents: a distilled 30B model with a perception encoder that fits consumer / workstation hardware (~18GB weights, 128K context), licensed Apache 2.0, and wired into Claude Code, OpenCode, Hermes Agent, and OpenClaw via ollama launch. Privacy, air-gap, and predictable unit cost become product features — not research projects.

What shipped (in business terms)

  • Always-on local agents: designed to keep working through multi-step jobs without round-tripping every token to a hyperscaler.
  • Tool discipline: schema-accurate function calling across long workflows — the difference between a demo chatbot and an agent that files tickets, edits code, or queries MCP tools.
  • Failure recovery: when a tool errors or returns nonsense, the model diagnoses and retries instead of freezing the run.
  • Multimodal: screenshots, charts, and documents go in alongside text — useful for ops consoles, invoices, and UI automation.
  • Controllable effort: dial reasoning strength up for hard tickets, down for latency-sensitive paths.
  • Licence: Apache 2.0 — a cleaner commercial story than many “open weights” cards with SaaS carve-outs.
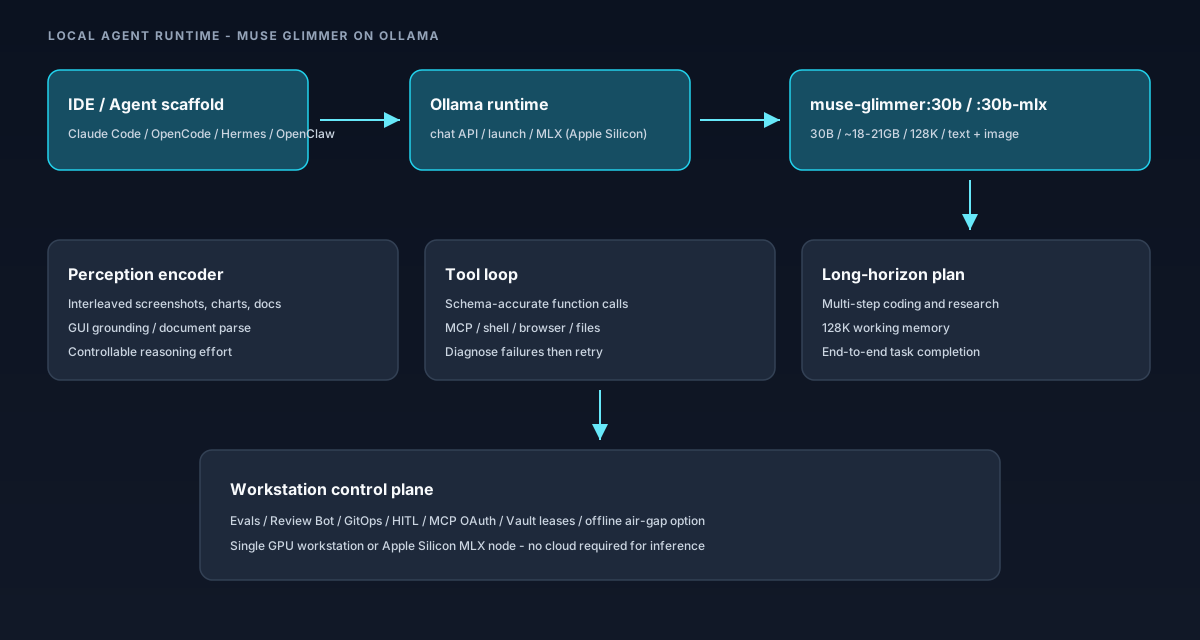
Muse Glimmer local agent stack from scaffold to Ollama

Why boards and SMEs should care

  1. Data residency: customer PII, source code, and financial docs can stay on the workstation or private VPC.
  2. Unit economics: inference cost becomes hardware amortisation + electricity, not per-token invoices that spike with agent loops.
  3. Continuity: offline or degraded-network sites (factories, clinics, field teams) keep agents running.
  4. Procurement clarity: Apache 2.0 + Ollama distribution lowers legal and ops friction versus opaque weight dumps.

Where it does not replace the cloud

Keep closed APIs (or larger open MoEs on a cluster) for peak-critical paths, brand-sensitive generation, and workloads that need vendor support SLAs. Muse Glimmer is the strong local / private lane in a hybrid router — not a mandate to rip out Bedrock or Anthropic overnight. Pair it with evals, HITL, and the controls in our agentic security brief.

Workstation advice

  • SMEs / Mac shops: start with ollama run muse-glimmer:30b-mlx on Apple Silicon (or the standard 18GB tag on a single mid/high GPU workstation).
  • Dev teams: wire scaffolds with ollama launch claude --model muse-glimmer (or OpenCode / Hermes / OpenClaw) and measure your golden tasks — not Meta’s leaderboard alone.
  • Enterprises: pilot air-gapped agent pods with Review Bot + GitOps; keep a cloud failover for overflow.

Full technical rewrite — architecture, Ollama tags, benchmark matrix vs Gemma4-31B / Qwen3.6-27B, Meta evaluation methodology, and a production checklist: long article. Published by Workstation.